conflict check software: running the check at intake
by the end of this, your intake form will search your own records, flag adverse parties, and surface a possible conflict before a staff member picks up the phone to call the person back. your client ledger never goes to a model. no model decides whether the conflict is real. a deterministic match against your own ledger does that, and a human clears it.
a lot of firms run the check after the first call. that is the wrong order, and it is worth being specific about why. if you already pay for conflict check software, keep it. this changes when the check runs and what feeds it.
the cost of running conflicts after the first call
here is the normal sequence at a lot of practices. someone calls in. a staff member takes down the basics: their name, what happened, who the other side is. that staff member is warm and already building rapport, because that is the job. the file goes to an attorney for review. the attorney runs the conflict check. three days later it turns out the firm represented the adverse party on an unrelated matter two years ago, or opposing counsel is someone the firm has a referral relationship with, or the "other driver" is a subsidiary of an existing client.
now the firm has to call back and say no. that conversation is worse for everyone than it needed to be. the prospective client has already told their story once, maybe twice. they have mentally hired you. and the firm has already spent staff time on a file that was dead from the moment the adverse party's name was captured, if anyone had checked it right then.
the conflict was knowable at intake. the information needed to catch it, names, entities, counterparties, is sitting in the first form or the first call script. the problem isn't that the data wasn't there. it's that nothing looked at it until a human had cycles to spare, which at a busy practice is always later than it should be.
the architectural split: extraction versus evaluation
this is the part that gets conflated, so i want to separate it cleanly.
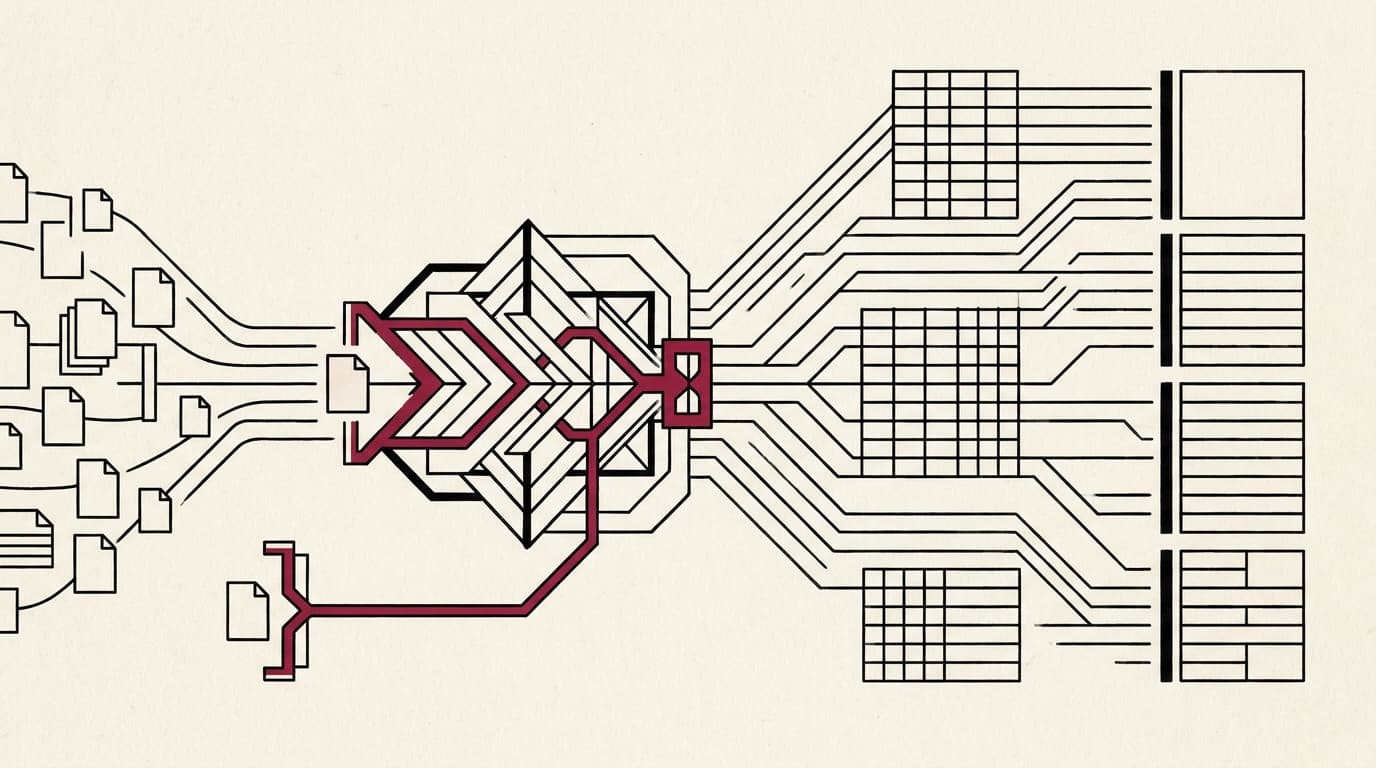
reading messy intake text and pulling out "this is a person's name," "this is a company," "this looks like an insurer" is a language problem. a model is good at that. it can take "my accident was with a guy driving for some bottling company, i think, or a distributor that works with them" and normalize it into something like: adverse party, individual, unspecified; adverse party, corporate, bottling company or distributor, name unconfirmed.
deciding whether that normalized name matches an existing client, a former client, or an opposing party on record is not a language problem. it's a lookup. it's exact-string and phonetic matching against a structured ledger the firm already maintains. that step has one job: return true or false, with a confidence level, against records that already exist. there is no reasoning to do. there is no judgment call a model should be making about whether this counts as a conflict under your jurisdiction's rules, because that is a legal determination, not a text-matching one.
so the model extracts. it never queries, and it never clears. a separate, deterministic function does the match, and a person does the clearance. that split is what makes the whole thing auditable: you can point at the exact match result that triggered a flag, independent of whatever the model said about it in plain language.
step 1: capture opposing parties cleanly on the intake payload
the intake form or phone script needs fields built for this, not a single open "tell us what happened" box. at minimum: the client's full name and any known aliases, the adverse party's name (individual and/or corporate), any insurer mentioned, and opposing counsel if the caller already has a name. a field for "related entities mentioned" catches the cases where someone says "it was a contractor working for the hospital," which is two entities, not one.
if your intake is a live call, this means the script prompts the staff member to ask these questions explicitly, rather than hoping the caller volunteers names in the right order. the goal is a structured payload at the end of the call, not a paragraph of notes someone has to parse later.
step 2: extract and normalize entities with an isolated model call
the raw payload goes to a model with one job: pull out every named person and entity, tag each as client, adverse party, insurer, counsel, or related entity, and normalize spelling and known aliases. "some bottling company, i think, or maybe a distributor" becomes a normalized entity string with a confidence flag, not a decision.
this model call has no access to your client ledger. it cannot look anything up. it reads text and produces structured output. that isolation matters: if the extraction step could also query your records, you'd have no clean boundary between "the model read something" and "the model decided something," and that boundary is the entire point of the system.
step 3: query the internal ledger with deterministic matching
the normalized entity list goes to a matching function that runs inside your own infrastructure, against your own client and matter records. this is where soundex or metaphone-style phonetic matching earns its keep, because "mcallister" and "mccallister" and "mc alister" are the same risk and a strict string match will miss two of the three. exact matches, phonetic matches, and matter cross-references all run here, and each one returns a record: which entity matched, which existing matter it touched, and how confident the match is.
nothing about this step involves a model making a judgment call. it is the kind of lookup a database has always been able to do. the only thing new is that it now runs before the callback instead of after.
step 4: stage the hit in a review queue with human gating
a match, even a high-confidence one, does not reject the file and it does not clear it. it stages. the callback holds, and a review card posts to whoever owns conflict checks at the firm, an ethics partner, an intake supervisor, whoever that is in your structure. the card shows the matched entity, the existing matter it touched, and the confidence level, so the reviewer is looking at the actual data the match was built from, not a model's summary of it.
this is the dry-run pattern: propose, stage, wait for a human. the system never auto-clears and it never auto-rejects. it surfaces what it found and gets out of the way.
step 5: fail safe to manual review when services degrade
if the extraction model is unavailable, or a match comes back ambiguous, the system does not guess and does not let the file proceed un-flagged. it fails to manual review. that means the default state when anything is uncertain is a human looking at the raw intake before a callback happens, not an automated green light. a conflict check that silently passes through when an api call times out is worse than no automation at all, because it looks like a check was run when it wasn't.
three common intake pitfalls that create silent conflicts
first, corporate parentage. callers rarely know or say the full legal name of the entity involved. "the trucking company" might be a subsidiary three layers down from a client you represent elsewhere. a matching system needs a path to flag ambiguous corporate entities for human research, not just drop them for lack of an exact hit.
second, misspelled or mis-transcribed adverse party names, especially on phone intake where names are heard, not typed. this is exactly why phonetic matching matters more than exact-string matching here. a system that only does exact matches will clear a conflict that a human would have caught by ear.
third, and this is the one that matters most: treating an automated "no match found" as ethical sign-off. it isn't. it's a tool that reduces what a human has to check by hand. the clearance decision, the actual determination that representation is proper, stays with the attorney responsible for that call, in whatever form your jurisdiction and your malpractice carrier require. nothing here is legal advice about what your obligations are, and rules on this vary by state. the system's job is to make sure the right information is in front of the right person before the callback, not to replace their judgment.
how to audit your intake pipeline
if your current process checks conflicts after the first conversation instead of before it, the fix usually isn't a new hire or a slower intake process. it's moving the check earlier and making it deterministic where it can be, with a clear seam between the step that reads and the step that decides. firms running conflicts after the callback usually aren't being careless. they built intake around the call and never revisited it once the volume grew. the full intake flow shows where this step sits, and why the ai should extract facts and never make the call goes deeper on the split.
if you want a second set of eyes on where your intake pipeline currently catches conflicts, and where it doesn't, the Workflow Audit is a two-week engagement built for exactly this kind of review, and the fee comes off a build if you go ahead within ninety days.